Post
16 Oct 2026
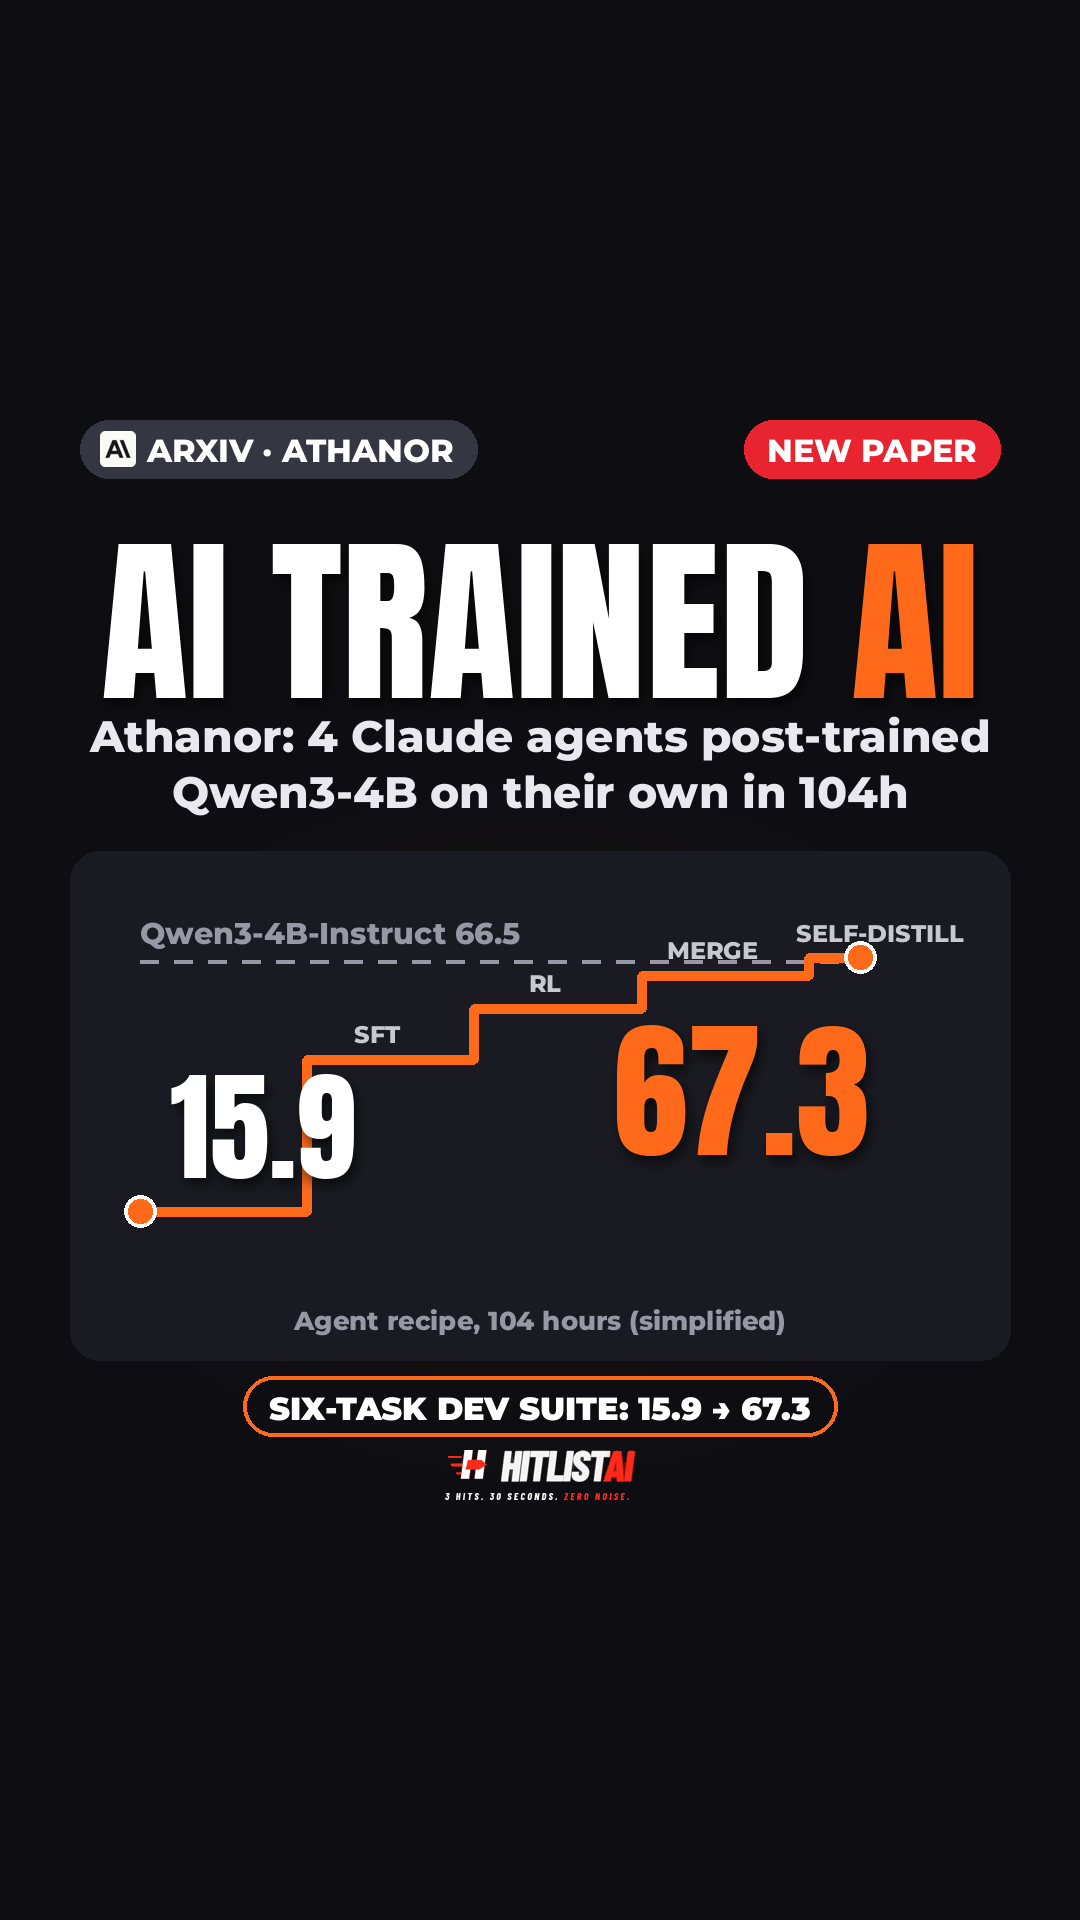
4 Claude agents post-trained Qwen3-4B to instruct level in 104h
ByteDance/Duke Athanor: four Claude Opus 5.5 agents, public data, no teacher models or human research advice, raised Qwen3-4B-Base from 15.9 to 67.3 on a six-task suite in 104 hours (Instruct 66.5) and 48.2 vs 47.9 held-out. Cost ~$11,800. Caveat: one campaign, not yet at Qwen reasoning releases.
 02Robotics
Physical Intelligence opens Pi API beta
Upload robot data, fine-tune a π model on managed compute, and run it via hosted inference. Early partners include Actor's wheel loader (no operator inside) and Almond's deburring robot after four days of iterating. Beta by application.
Physical Intelligence · pi.website ↗ (opens in a new tab)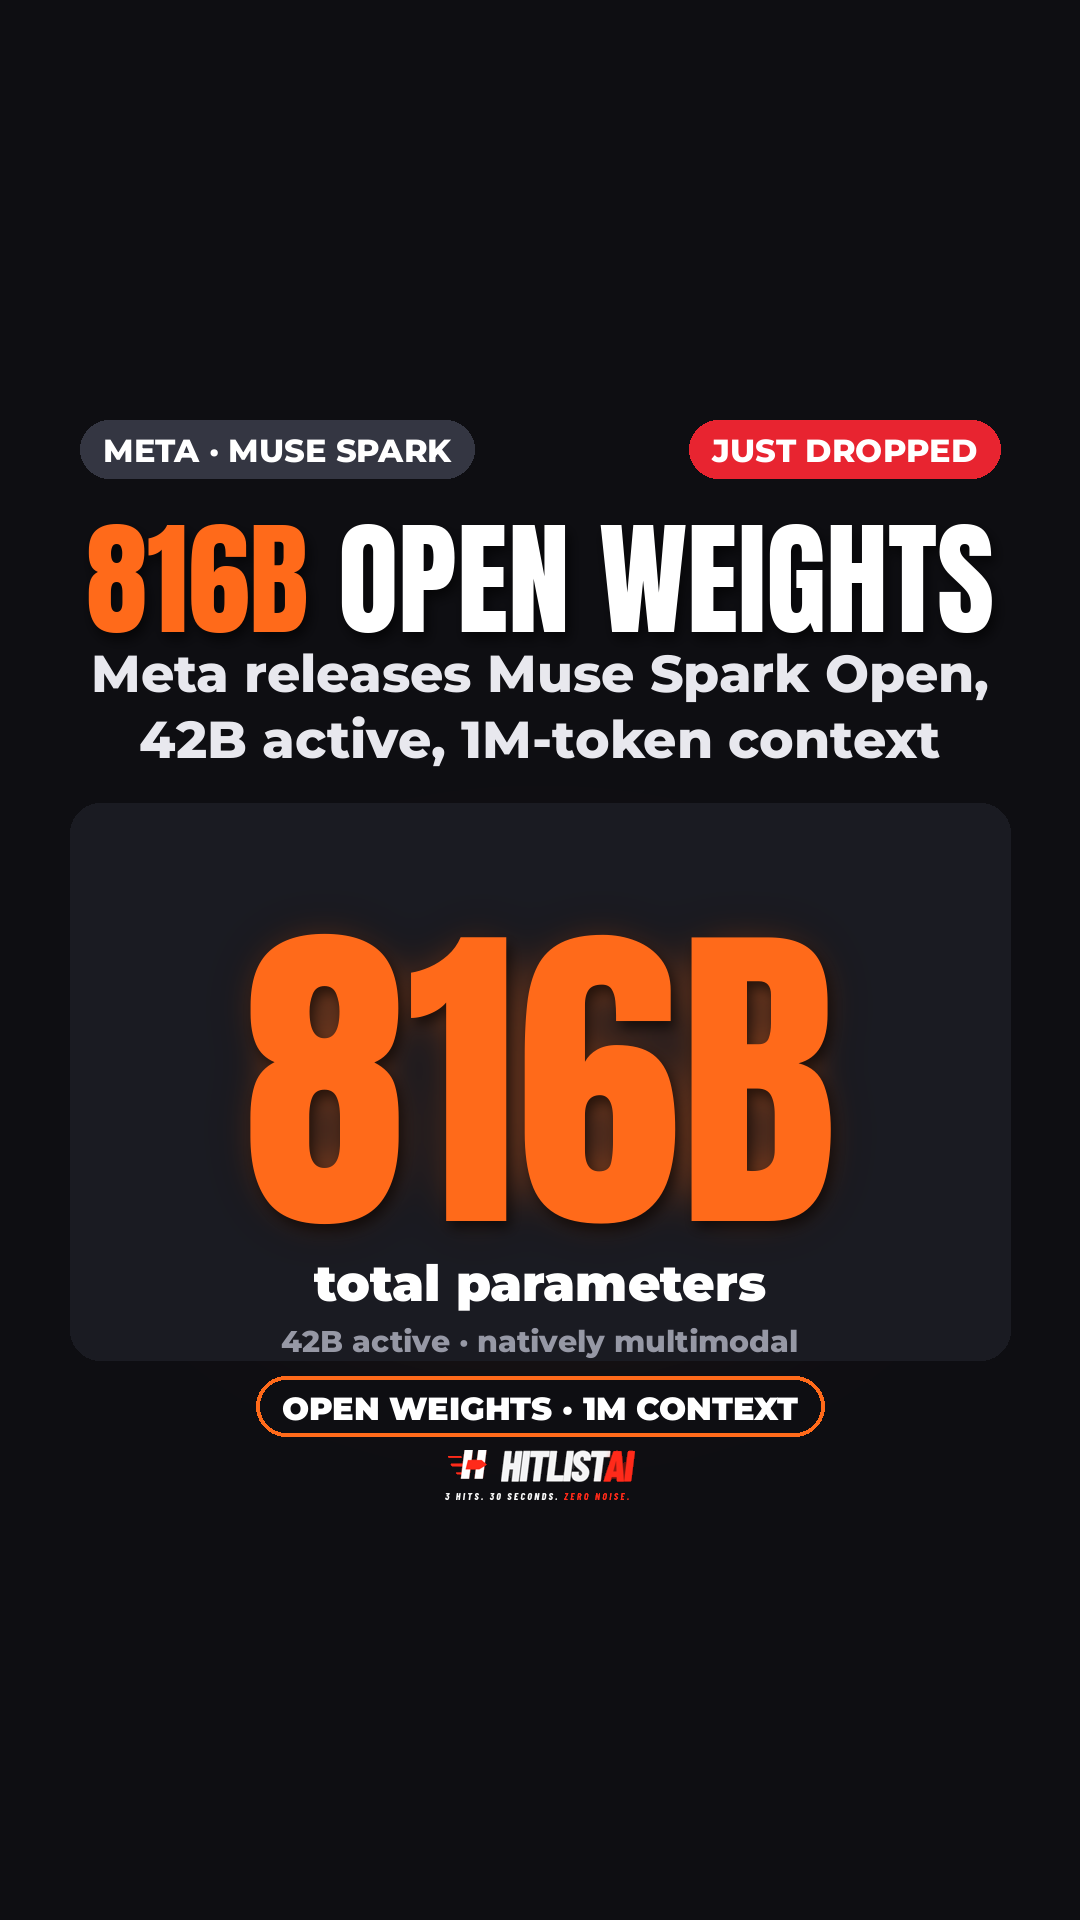
Meta open-weights Muse Spark Open: 816B / 42B active
Natively multimodal with a 1M-token context, built for coding and agentic work. First in its class to run on two Apple M5 Ultra Mac Studios with MLX; APIs and Hugging Face weights live under the Muse Model License.
Meta AI Research · research.meta.ai ↗ (opens in a new tab)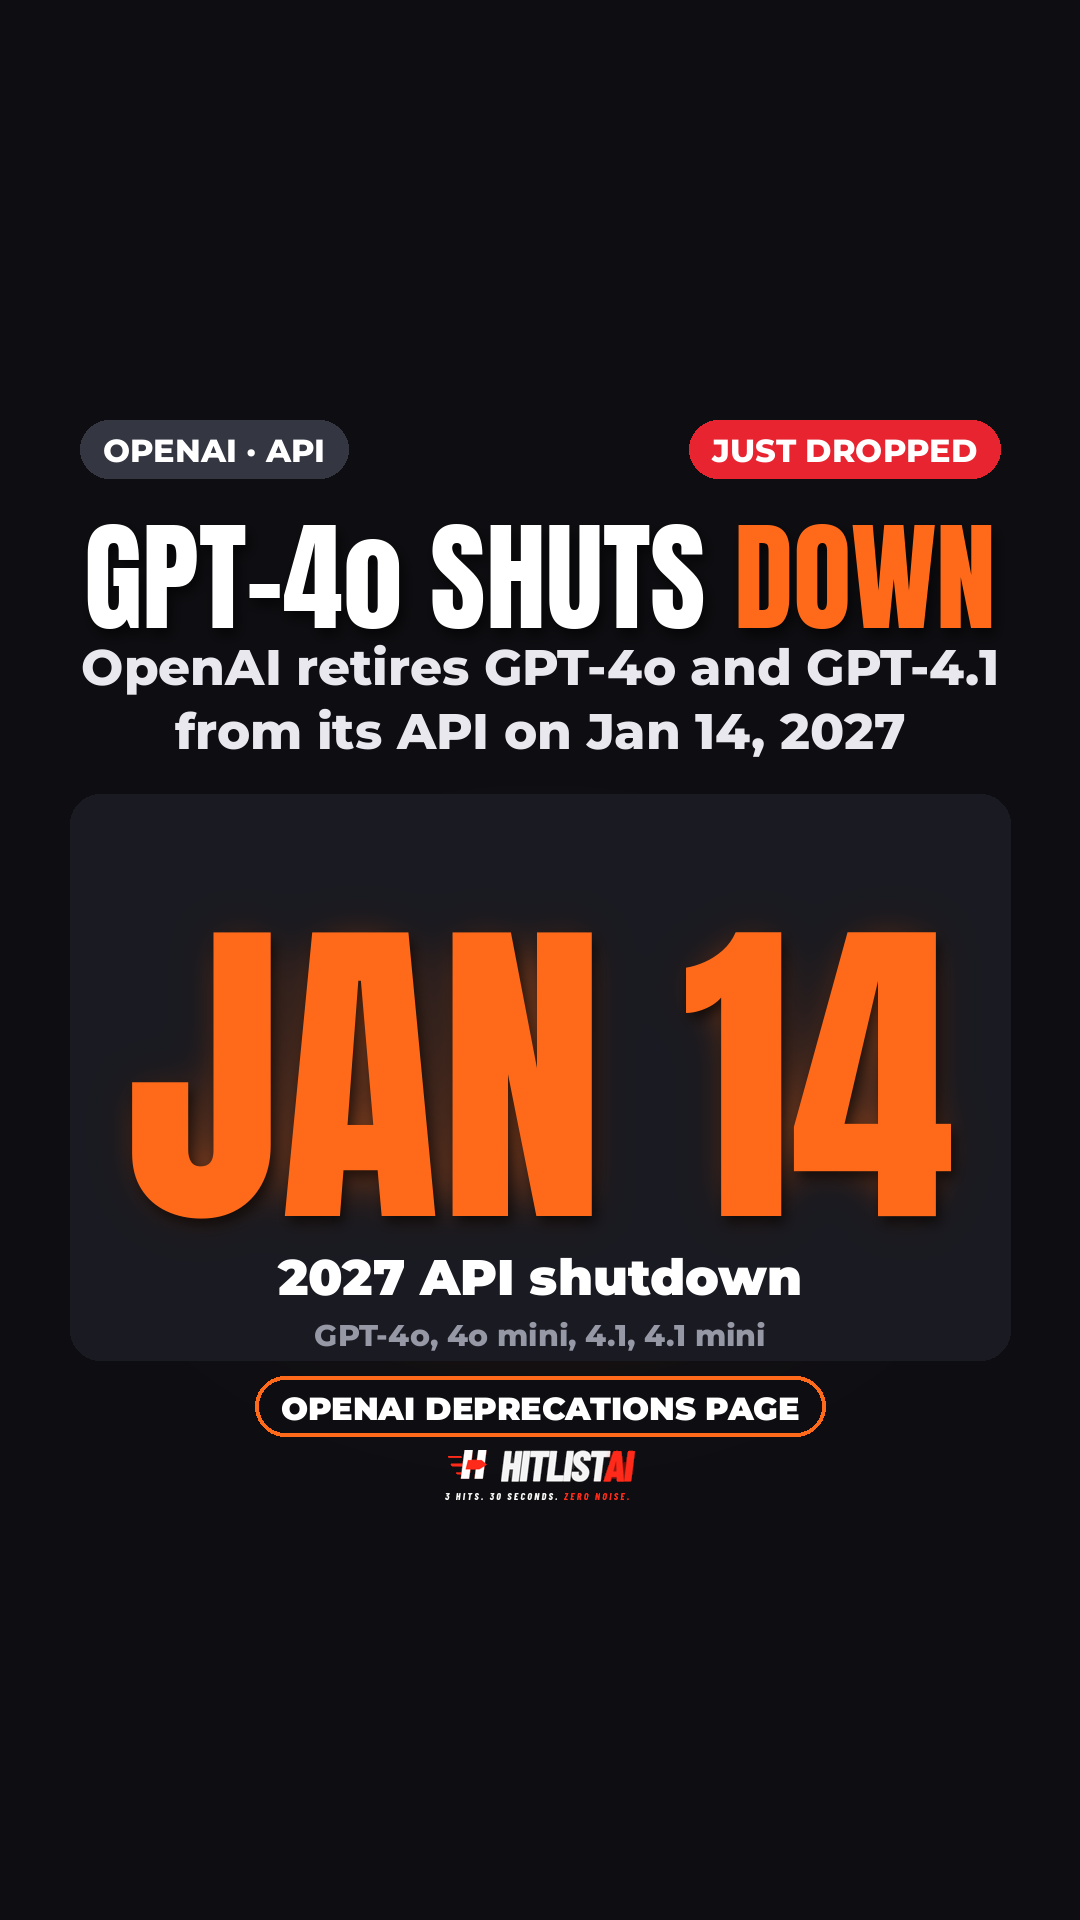
OpenAI is retiring GPT-4o from its API on Jan 14, 2027
Deprecated Oct 14: gpt-4o snapshots, gpt-4o-mini, gpt-4.1 and gpt-4.1-mini shut down January 14, 2027; fine-tunes follow the same schedule. Recommended replacement: gpt-6-luna.
OpenAI · developers.openai.com ↗ (opens in a new tab)
StepFun open-weights Step 5 Preview: 600B, 27B active
Sparse MoE with up to 1M tokens of context for repo-level coding, long-horizon agents and finance. Serving examples start at four B300 GPUs (FP8) via vLLM or SGLang; StepFun Model License 1.0.
Hugging Face / StepFun · huggingface.co ↗ (opens in a new tab)
Black Forest Labs FLUX 3 Klein: 5.6B open image model, 8GB GPUs
Text-to-image, editing and up to 10 reference images, native 4K and bounding-box control. INT8 runs on GeForce RTX with as little as 8GB VRAM. Free commercial use under $5M annual revenue (FLUX Kommunity License).
Black Forest Labs · bfl.ai ↗ (opens in a new tab) 07Agents
Perplexity open-sources SPACE, the sandbox behind its agents
Apache 2.0 sandbox platform behind Computer: each sandbox is a small VM with its own OS; credentials and network stay outside. Perplexity cites millions of sandbox creations a day, 3–5x faster than its previous provider.
Perplexity · perplexity.ai ↗ (opens in a new tab) 08Models
Liquid AI d1-ultra answers with probabilities, not text
Multimodal decision model: text and/or images plus questions → probability per answer in one forward pass, no generated tokens. Liquid says it beats Jev 1.14 on all its tasks and leads the Artificial Analysis Decision Index by 8+ points. $0.042 per 1M input tokens.
Liquid AI · liquid.ai ↗ (opens in a new tab) 09Safety
Anthropic lets METR evaluators inside, with no publication veto
Six METR staff get employee-like access (hardware, office, internal tools on par with Anthropic risk teams). METR publishes analysis of risk levels, incidents or practices; Anthropic can't veto, only require narrow predefined redactions. Also working with SecureBio and Accenture.
Anthropic · anthropic.com ↗ (opens in a new tab) 10Voice AI
xAI Grok Voice 3.0 tops the speech-to-speech index at $0.08/min
Speech-to-speech voice agents with sub-second latency. #1 on Artificial Analysis Speech-to-Speech Index (86.9); 71.6% on τ-Voice. Starlink call centers: 20,000 calls/day, ~70% resolved with no human. Same price as Grok Voice 2.0.
xAI · x.ai ↗ (opens in a new tab) 11Voice AI
OpenAI ships GPT-Live-1.1 for ChatGPT Voice
New Live voices in French, German, Hindi, Japanese, Korean and Mexican Spanish, more natural accents, and fewer filler "checking…" moments. In ChatGPT Voice, Codex and dots; API coming soon.
OpenAI · x.com ↗ (opens in a new tab) 12Research
Goodfire: neural networks may already be interpretable
A working hypothesis: in preliminary audits ~90% of Qwen3-32B neuron poles have one main job, so understanding AI from the inside may be far more tractable than assumed.
Goodfire · already-clean.goodfire.com ↗ (opens in a new tab) 13Research
OpenAI opens GPT-Rosalind to US university labs
Eligible U.S. academic labs get up to 30 free seats for up to 12 months and trusted access to OpenAI's life sciences model, lowering the cost of AI for basic biology research.
OpenAI · openai.com ↗ (opens in a new tab)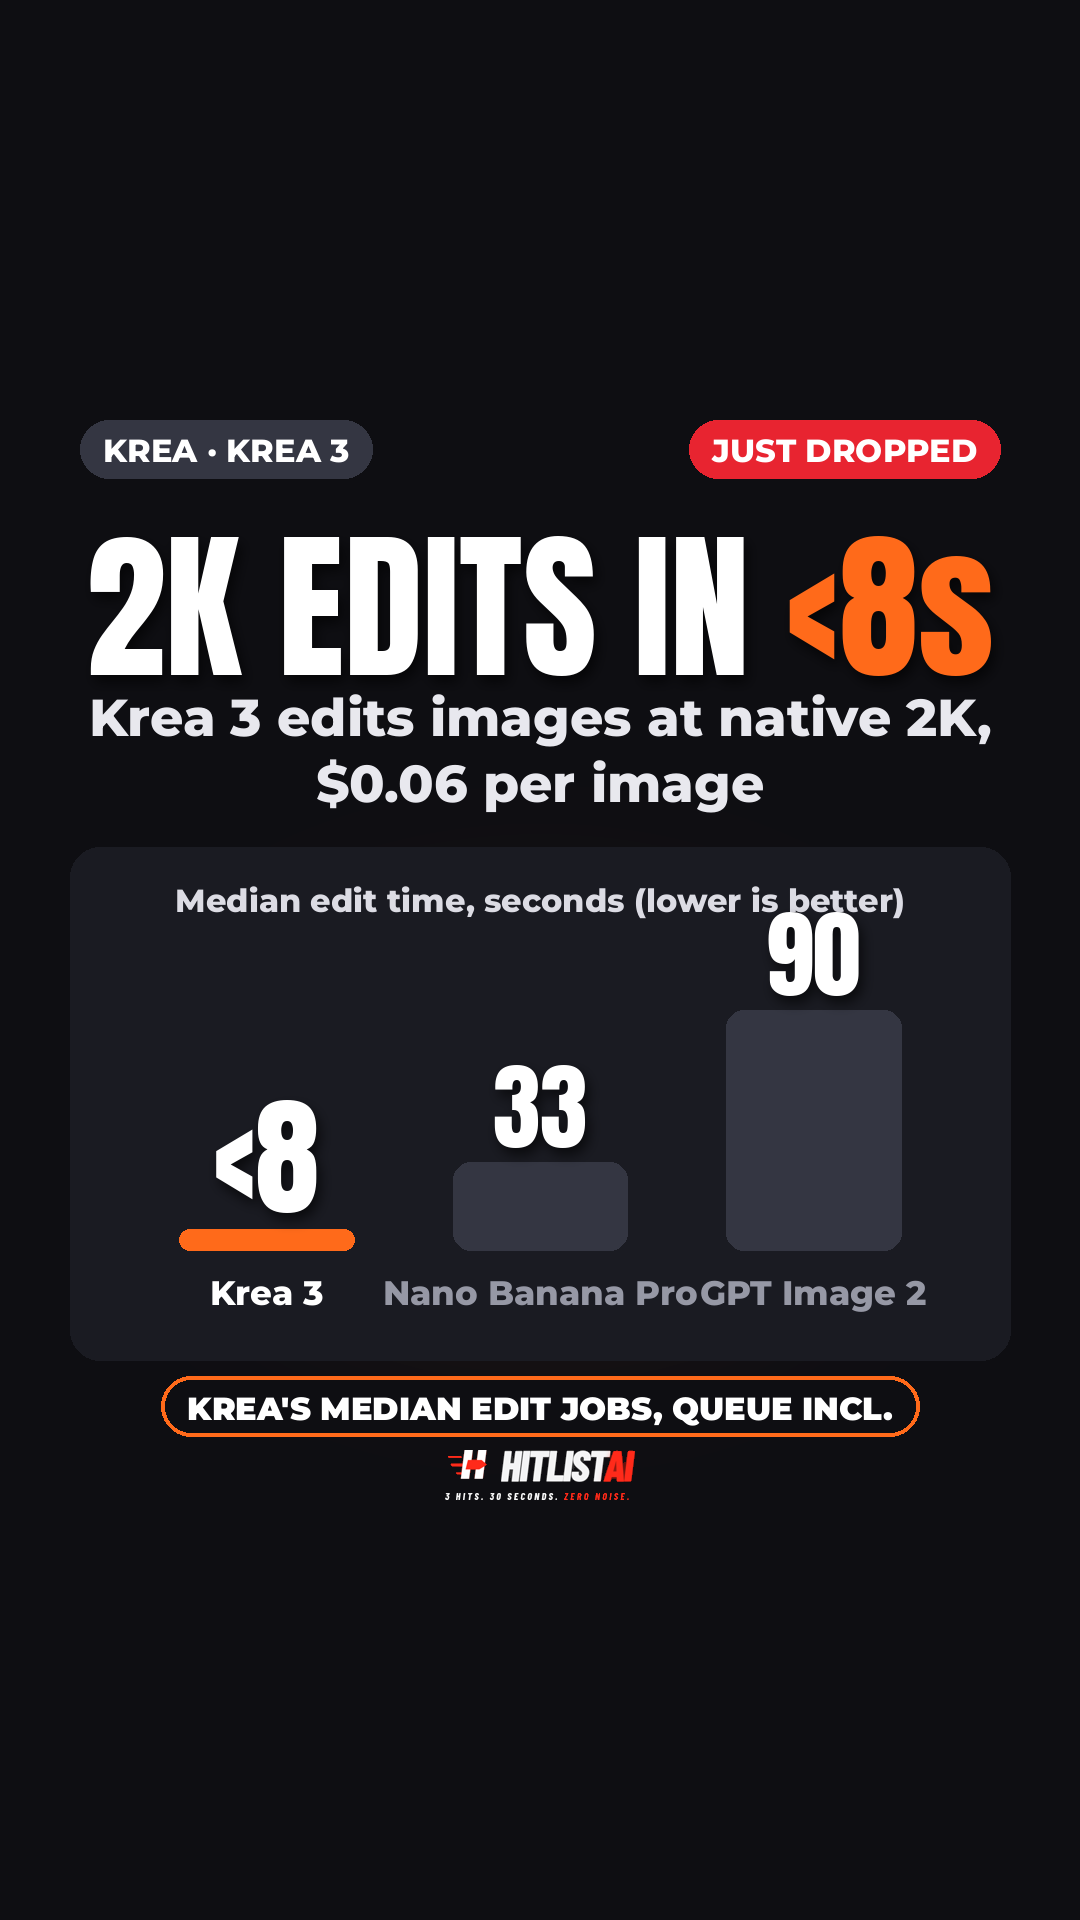 14Vision
Krea 3: under-8s image edits at native 2K
Krea's new editing model finishes most edits in under 8 seconds at native 2K for $0.06, keeping products and characters consistent so creative teams can iterate at catalog scale.
Krea · krea.ai ↗ (opens in a new tab) 15Research
CERN and Mistral plan a Large Physics Model
CERN and Mistral signed a statement of intent to build the first foundation model for collider physics, trained on billions of simulated LHC collisions, to learn across a reconstruction chain that today relies on specialised algorithms.
CERN · home.cern ↗ (opens in a new tab) 16Security
Websites send prompt injections to AI agents in HTTP headers
A scan of 217 million web responses found 7,959 sites sending headers aimed at AI agents and 30 injection attempts; agents that read the web should treat headers as untrusted input.
Signals Corps · signalscorps.com ↗ (opens in a new tab) 17Models
TypeSafe Jev 1.14 adds images, boxes, long context
Jev 1.14 ships experimental image input, a bounding-box type, and longer context behind danger-zone flags, plus quieter multilingual gains on the core decision model.
TypeSafe AI · typesafe.ai ↗ (opens in a new tab) 18Tools
DigUp brings local AI file search to Windows and Linux
DigUp 0.7 beta puts EmbeddingGemma 2 multimodal search on Windows and Linux so you can find photos, PDFs, audio, and video by meaning—on device, no account.
DigUp · github.com ↗ (opens in a new tab)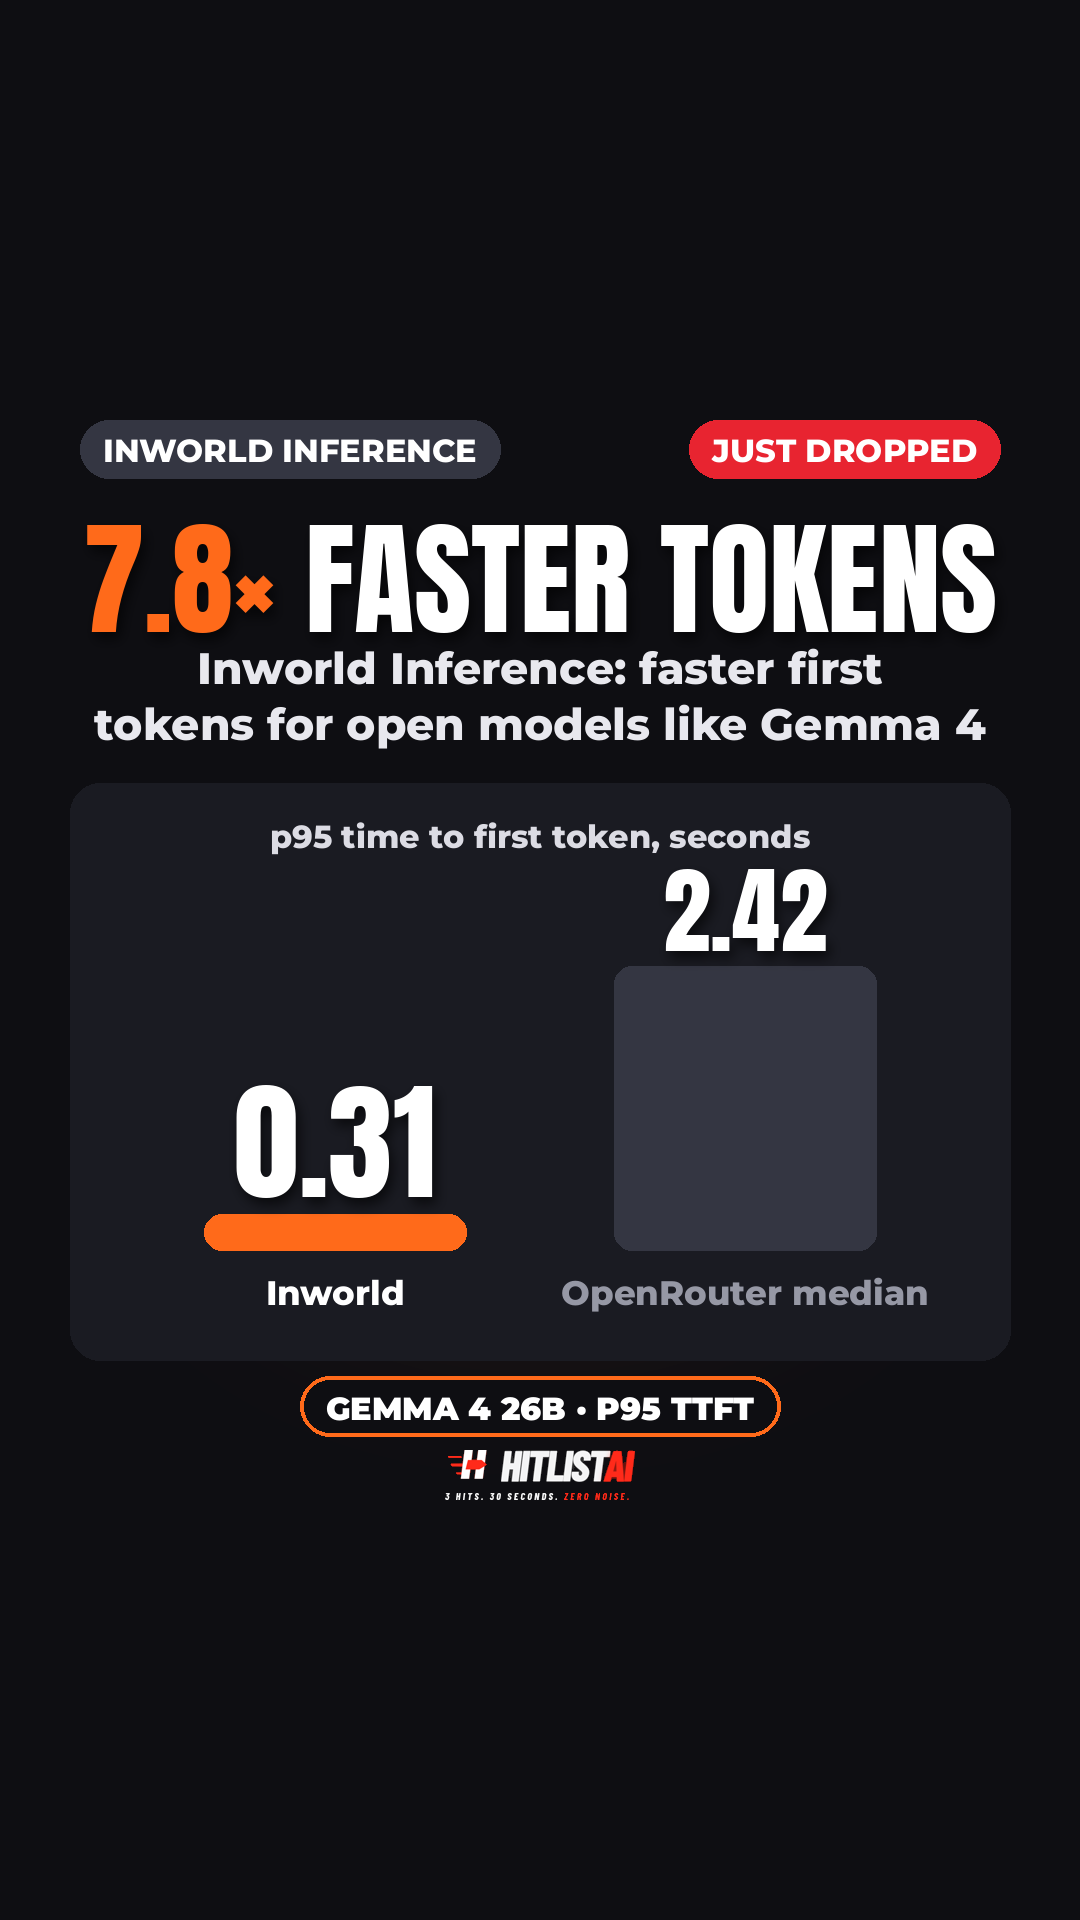
Inworld Inference: 7.8× faster open-model first tokens
Inworld opened its consumer-AI inference API to all developers, reporting 7.8× faster p95 first tokens on Gemma 4 26B vs the median OpenRouter provider, with heavy prompt caching.
Inworld AI · inworld.ai ↗ (opens in a new tab)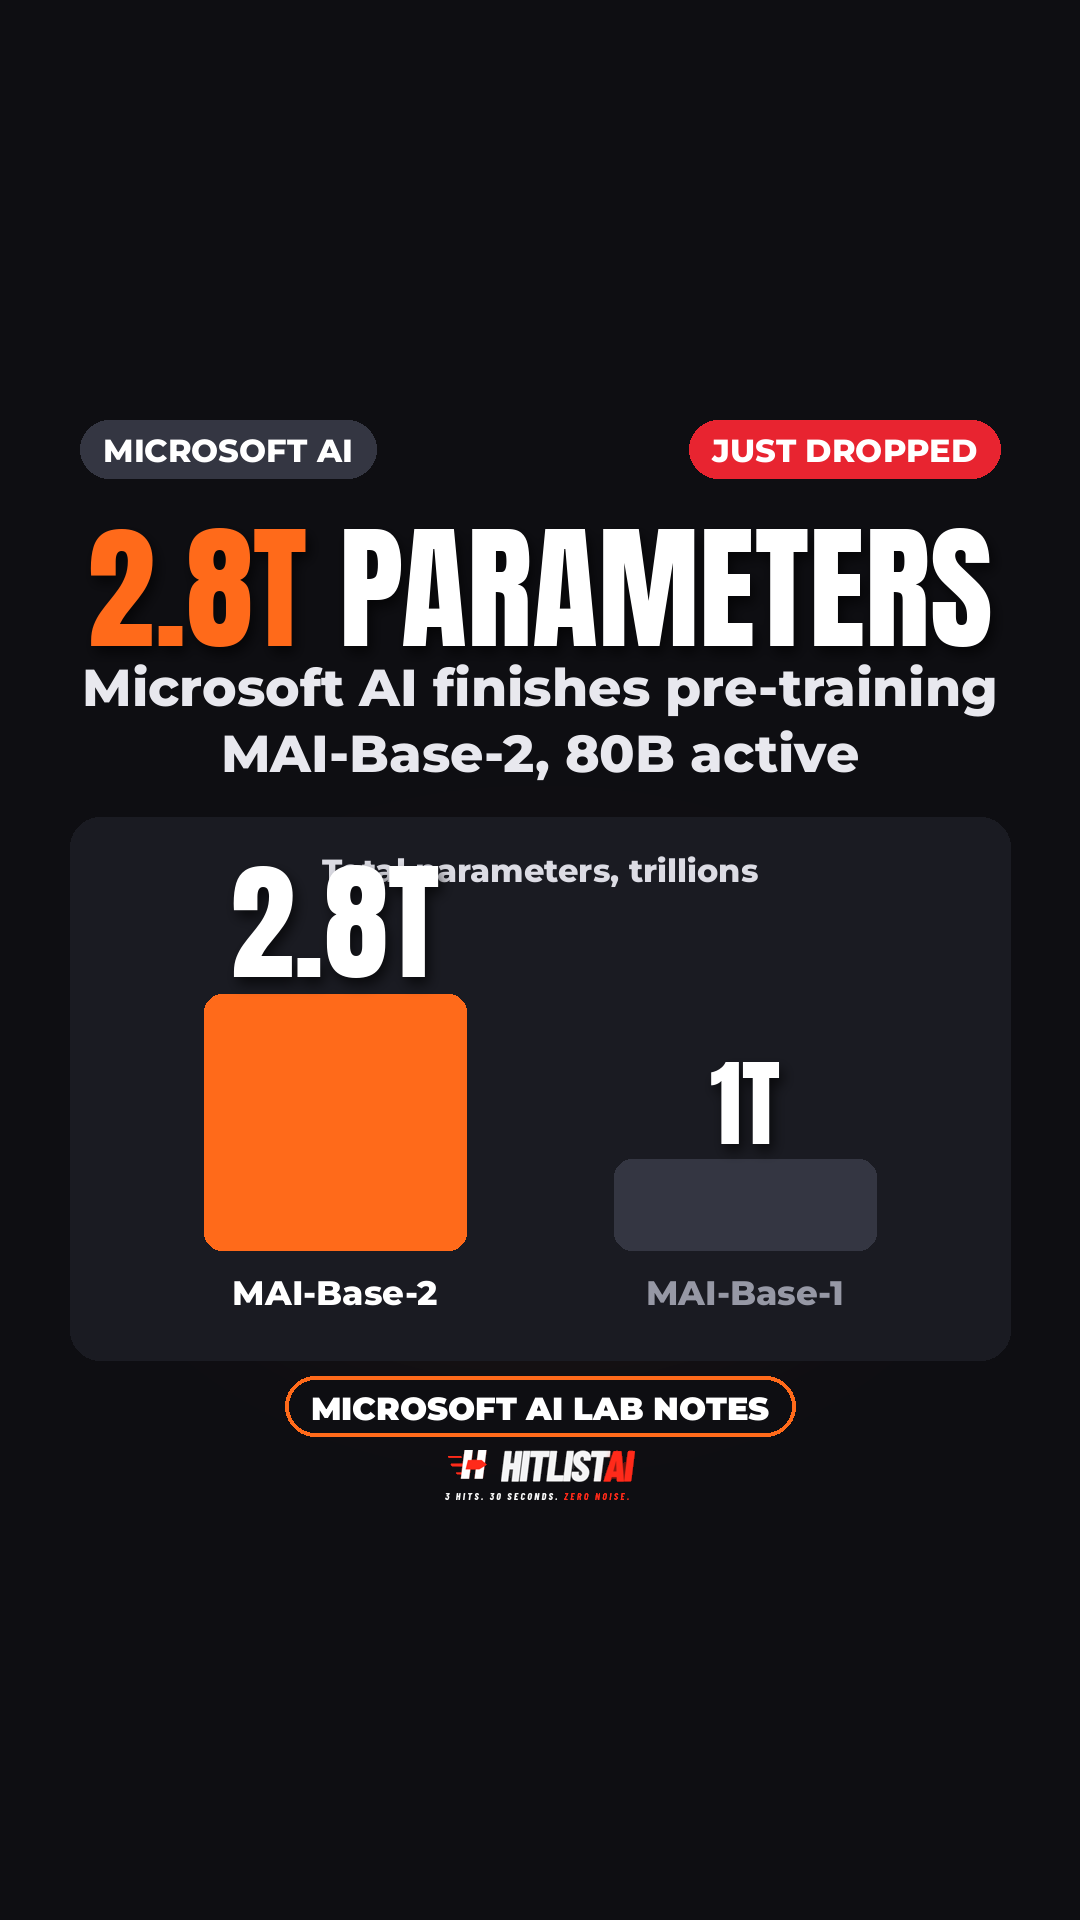 20Models
Microsoft finishes pre-training 2.8T-parameter MAI-Base-2
Microsoft AI's new in-house MoE base model (80B active, 2.8T total) beats every open-weight model it tested on its own held-out evals and is 4-12x more compute-efficient than DeepSeek-V4-Pro-Base, per Microsoft; it is now in post-training.
Microsoft AI · microsoft.ai ↗ (opens in a new tab)
Ant Ling open-sources 560B Ling-3.1-flash under MIT
Ling-3.1-flash is a 560B hybrid-linear MoE (about 25B active, up to 1M context) released with MIT-licensed open weights on Hugging Face and ModelScope, aimed at agents, office work and coding.
inclusionAI / Ant Ling (Hugging Face) · huggingface.co ↗ (opens in a new tab)
Mistral's Timestral: 209M forecasting model tops 3 benchmarks
Mistral's first time-series foundation models (5M–209M params) run on a CPU; Mistral says the 209M model ranks first on GIFT-Eval, TIME and fev-bench with two-thirds the parameters of the previous best.
Mistral AI · mistral.ai ↗ (opens in a new tab) 23Agents
Datadog Scout 1.0: AI SRE model claims frontier quality, 3-8x cheaper
Datadog's first incident-investigation model (built on GLM-5.3 Flash) matches GPT-6.1 Sol high and Claude Opus 5.5 high on its internal AlertEval benchmark at 3–8× lower estimated cost, per Datadog; in closed preview.
Datadog · datadoghq.com ↗ (opens in a new tab) 24Research
Google Deep Review: public AI that stress-tests technical docs
Google Research launched Deep Review publicly after 16,000+ conference-submission pilots; 2 free reviews/week, PDFs/plain text, uploads not used for training; Google cites 74k+ AI-conference submissions this year.
Google Research · research.google ↗ (opens in a new tab) 25Coding
Claude Code Review is GA for Team and Enterprise
Anthropic took Code Review out of research preview for Team and Enterprise; auto PR reviews via GitHub App; ~3× faster (20→6–10 min) per Anthropic; Enterprise credit promo ≥$10k by Jan 15, 2027.
Anthropic · claude.com ↗ (opens in a new tab) 26Models
Claude Opus 5.5 fast mode: no waitlist, up to 2.5×
Anthropic removed the waitlist for Opus 5.5 fast mode (Oct 15): same weights, up to 2.5× OTPS at $8/$40 MTok; Claude API + Azure Foundry; Start/Build/Scale get a default fast rate limit.
Anthropic · platform.claude.com ↗ (opens in a new tab)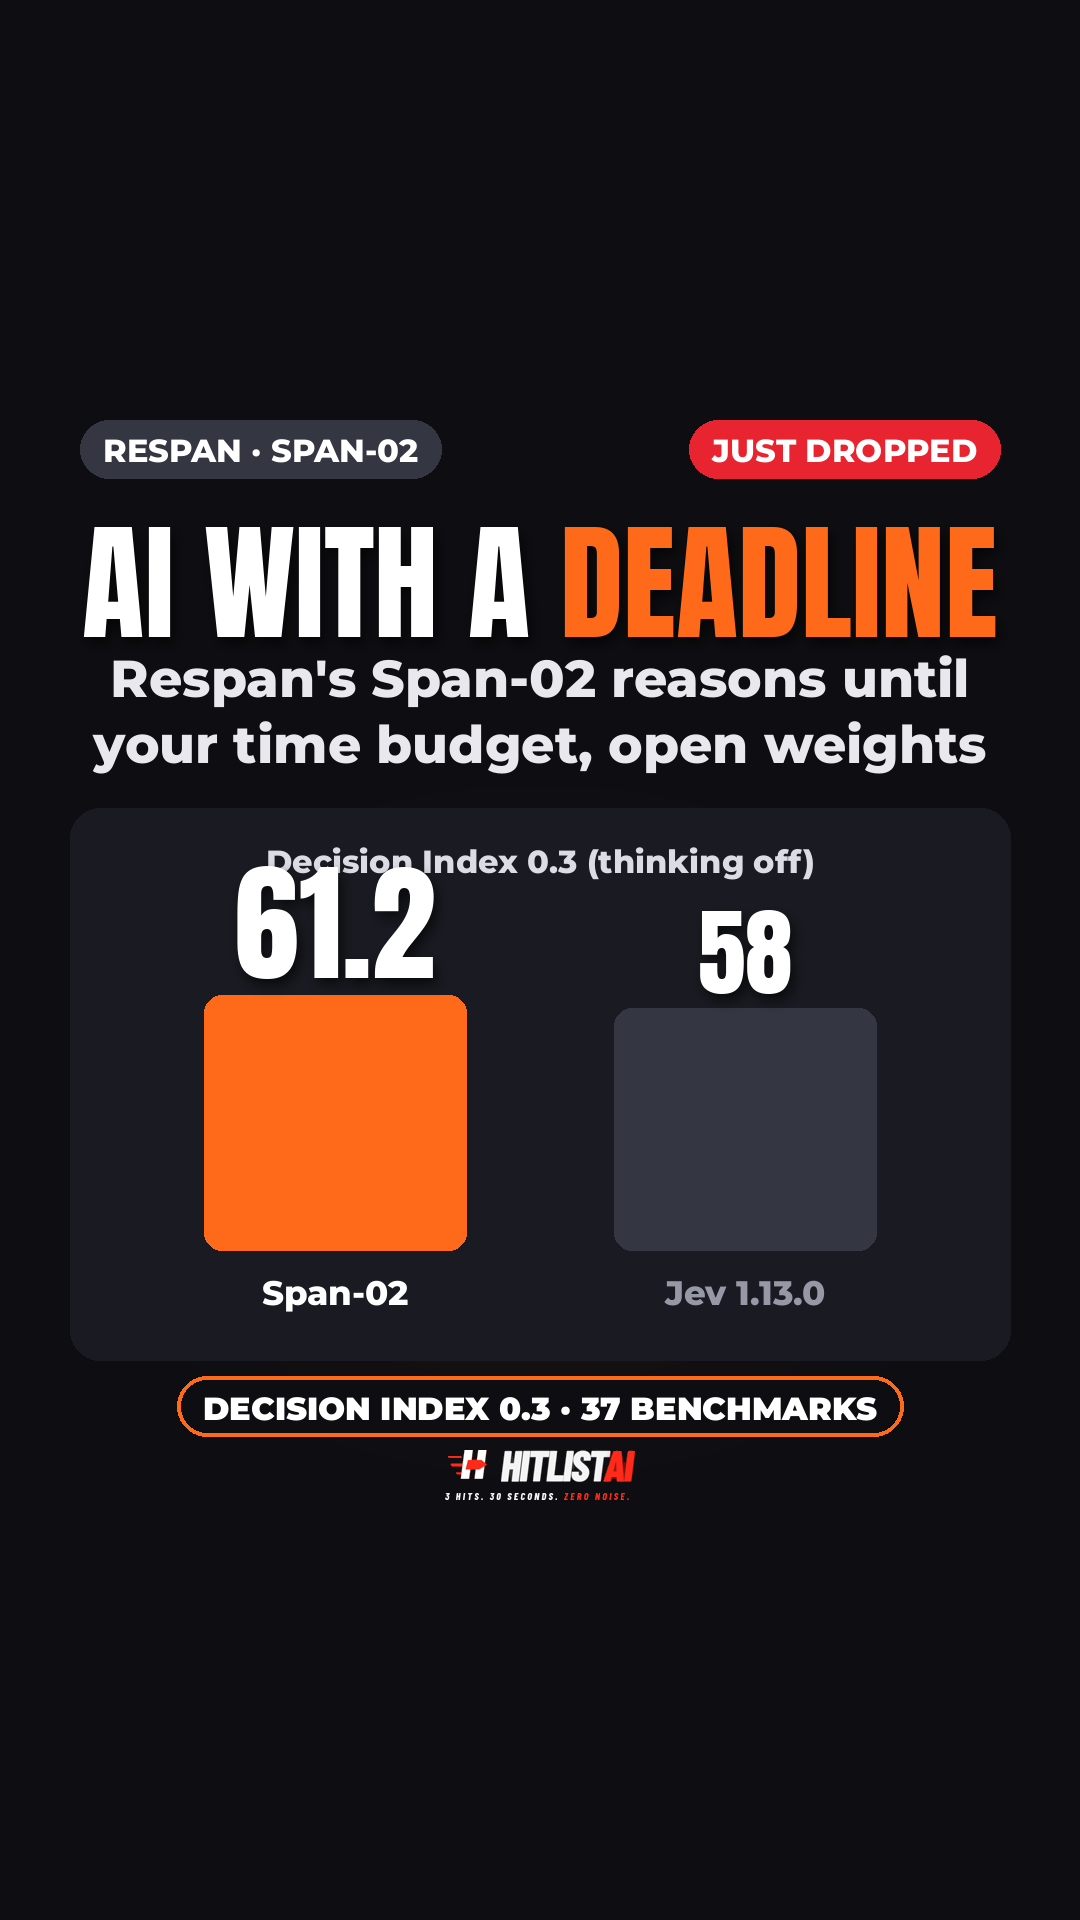
Span-02: open-weight decisions with a thinking deadline
Respan released Span-02 (Oct 15): open-weight decision model with budget_ms anytime reasoning; Decision Index 0.3 61.2 (off) / 64.1 (no limit) vs Jev 58.0; Blind Earth 71.9%→84.7% at 1s.
Respan · respan.ai ↗ (opens in a new tab) 28Research
Sakana open-sources The Agentic Scientist for AI-run research
Sakana AI's next AI Scientist orchestrates coding agents with rubrics, shared memory, ablations and an evidence map; a co-discovered paper was accepted as an ALIFE 2026 oral, and the code is open source.
Sakana AI · pub.sakana.ai ↗ (opens in a new tab)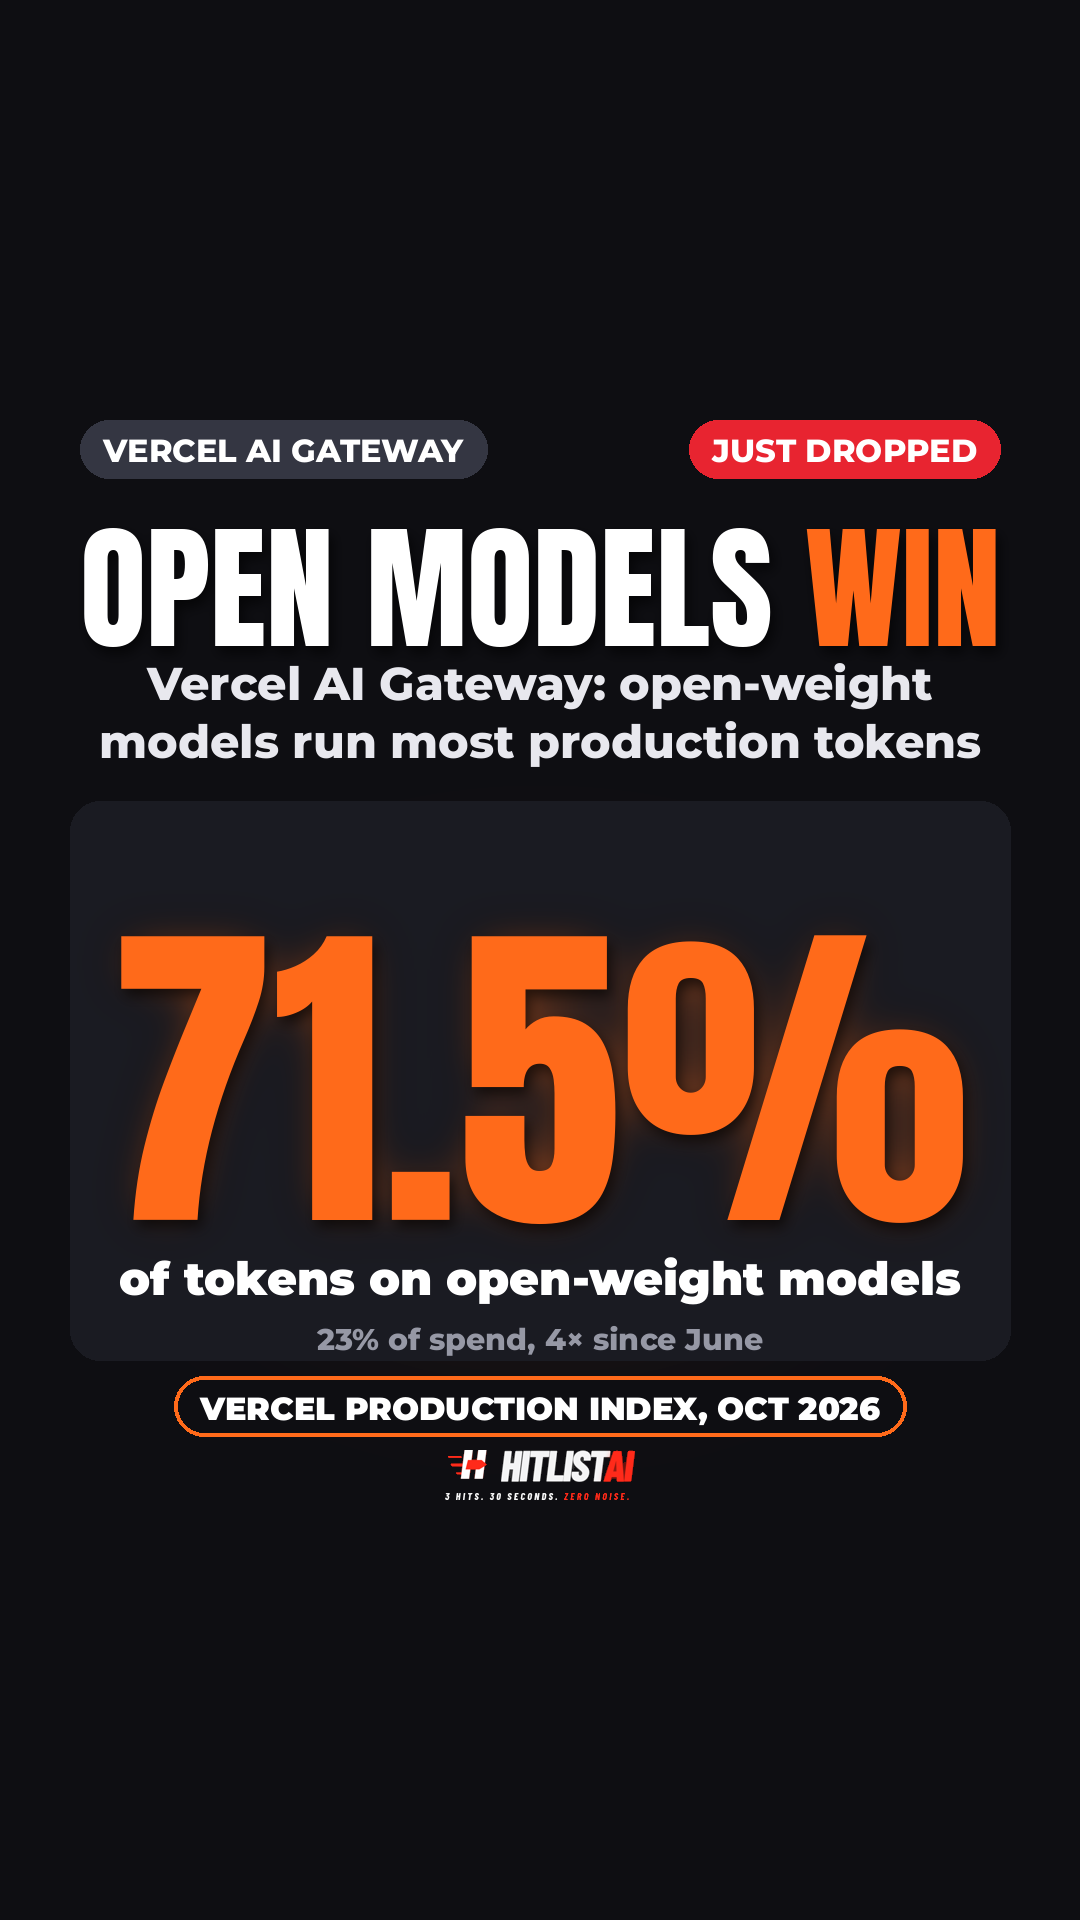 29Business
Open-weight models now run 71.5% of Vercel AI Gateway tokens
Vercel's October Production Index: open weight took 71.5% of tokens and 23% of spend (4x+ since June); spend ~13x December as price per token fell 47%; Anthropic's spend share fell below half.
Vercel · vercel.com ↗ (opens in a new tab) 30Voice
ElevenLabs Instant Soundtracks scores your video and adds SFX
Upload a video and ElevenLabs writes original music, then places sound effects at the right timestamps; it can follow existing audio as a reference. Live in ElevenCreative, ElevenMusic and the API.
ElevenLabs · elevenlabs.io ↗ (opens in a new tab)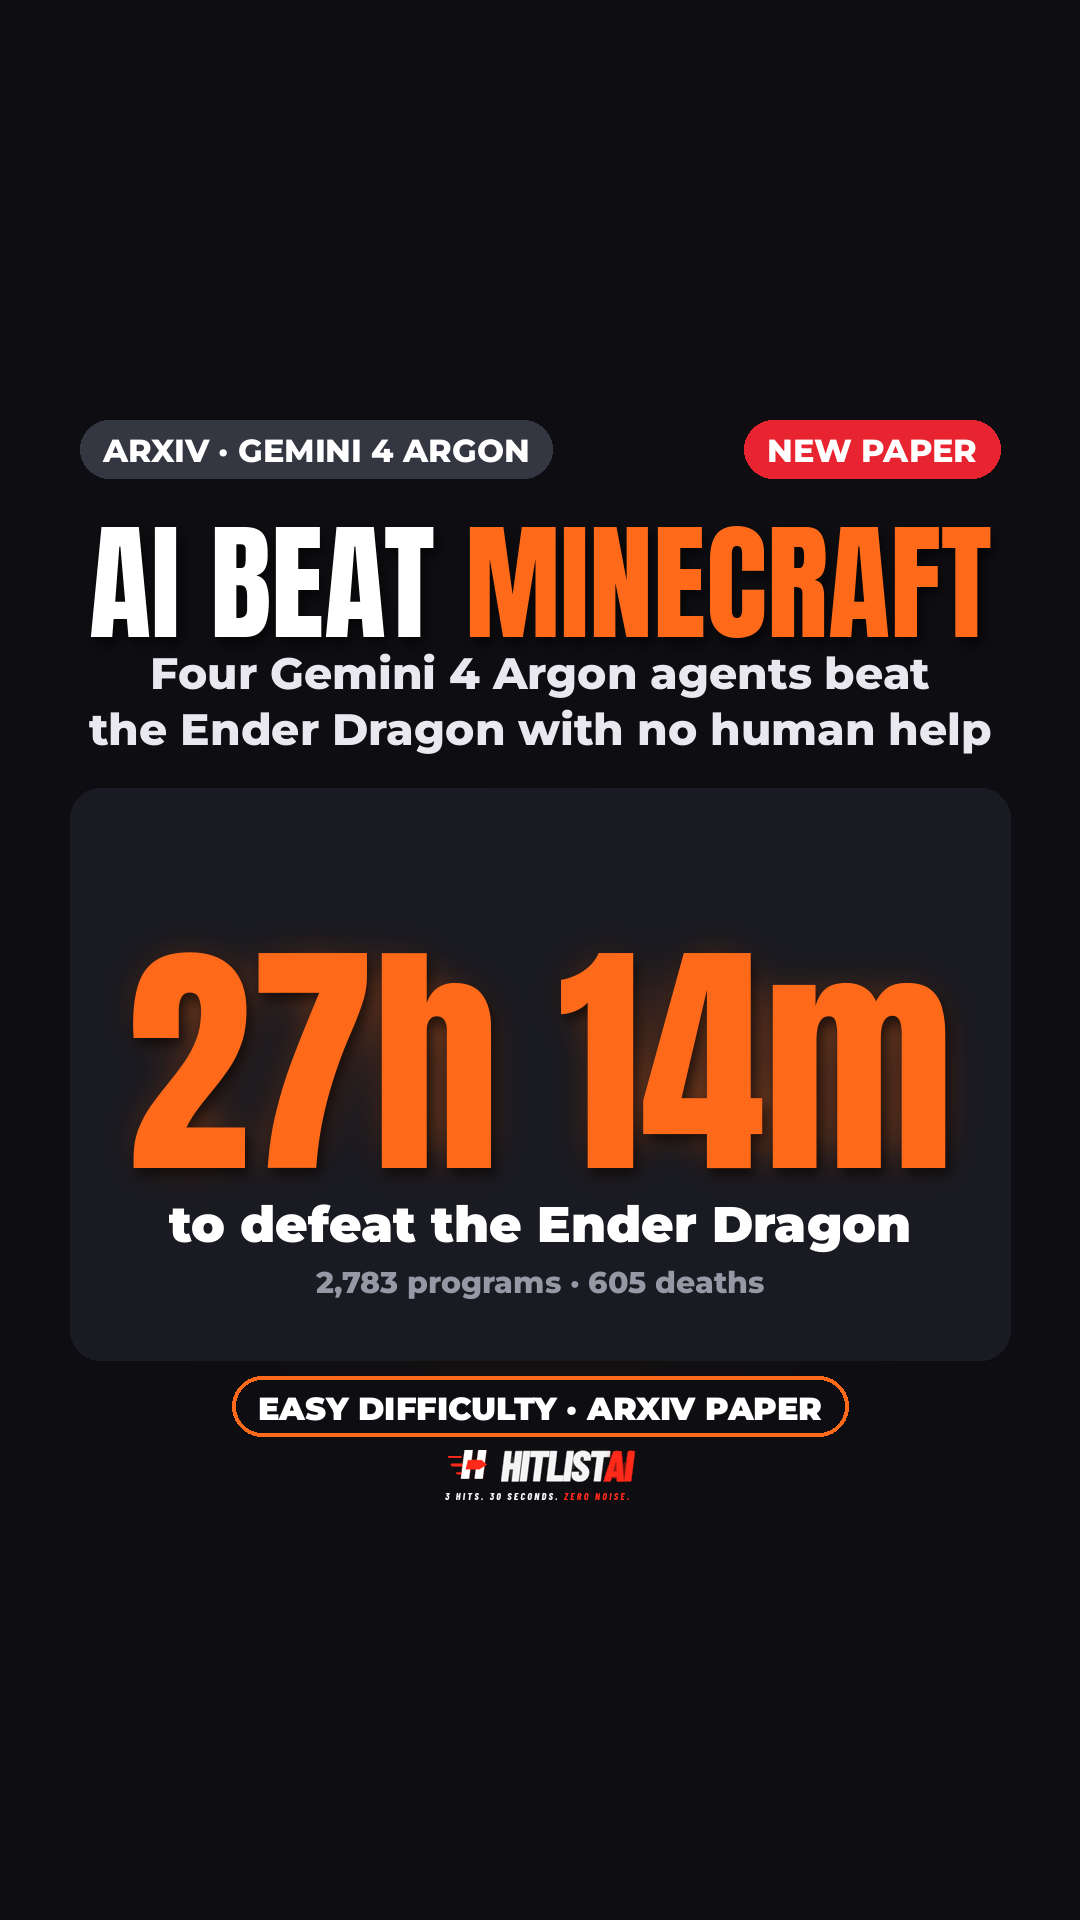 31Agents
Four Gemini 4 Argon agents beat Minecraft in 27 hours
In a new arXiv paper, four Gemini 4 Argon coding agents went from a random world to defeating the Ender Dragon in 27h 14m, writing 2,783 programs with no human input. Caveats: one run, Easy mode.
arXiv · arxiv.org ↗ (opens in a new tab)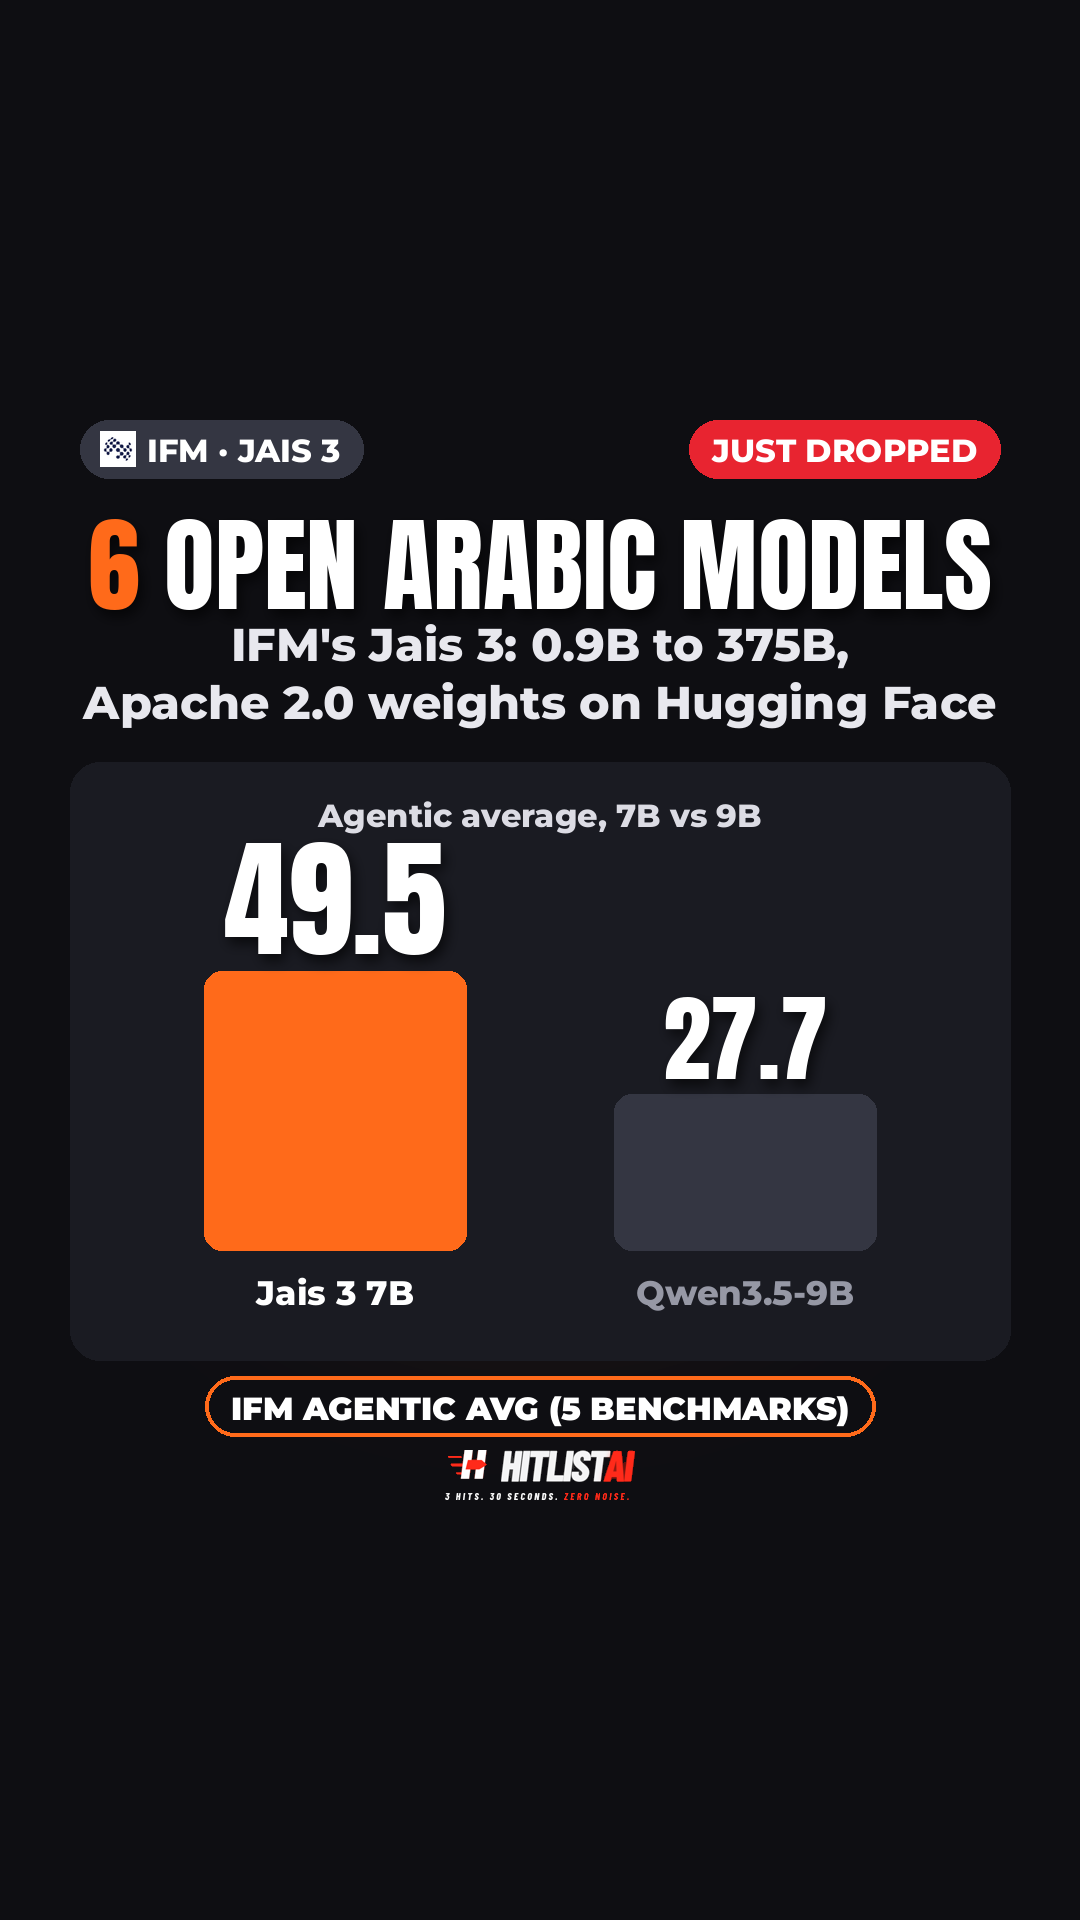
Jais 3: six open Arabic agent models up to 375B
IFM and Inception42 released six open Arabic-centric models from 0.9B to a 375B MoE (23B active), 512K context, built on K2 Horizon. Their eval: 375B leads open models at 84.0 Arabic average; 7B leads its size class on agentic tasks. Apache 2.0 on Hugging Face.
IFM / MBZUAI · ifm.ai ↗ (opens in a new tab)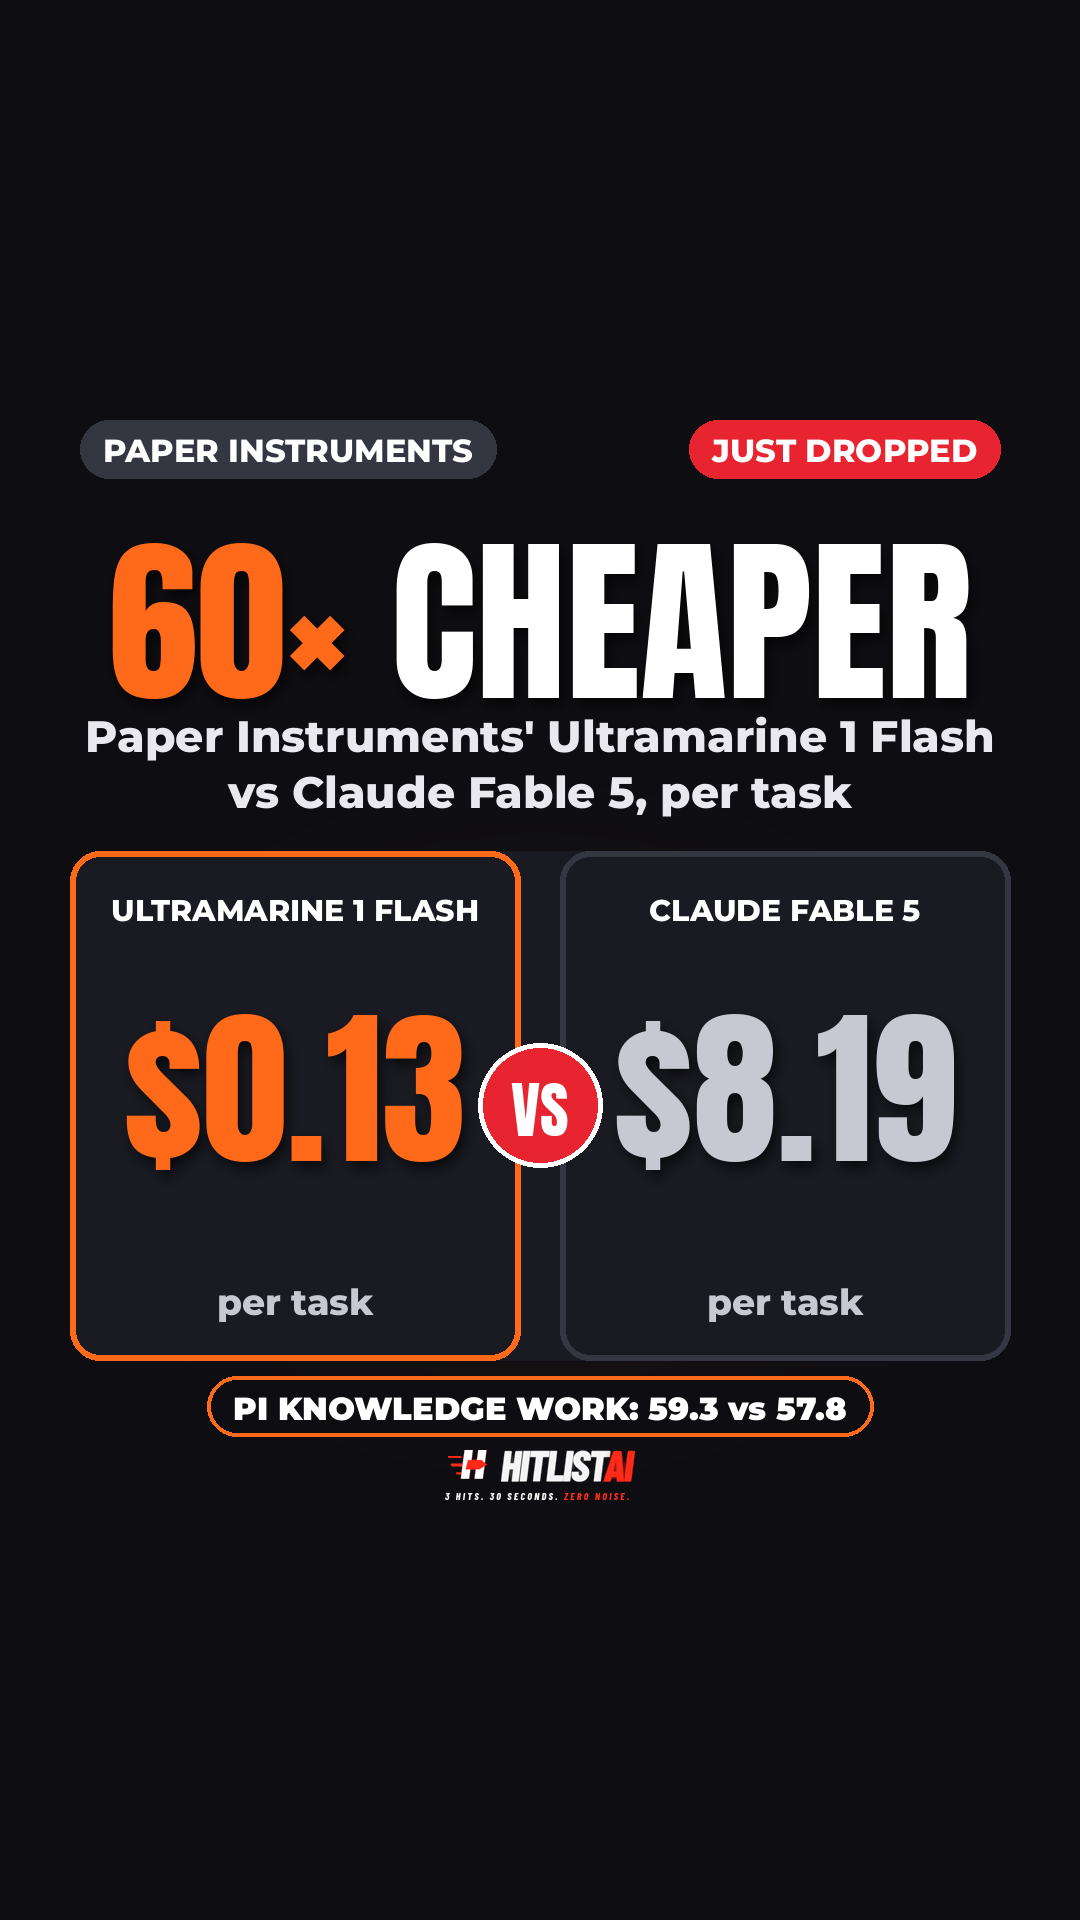
Ultramarine 1 Flash: Fable-class work at $0.13/task
Paper Instruments RL-trained open GLM-5.3 Flash for finance, law, consulting, and ops: +4.1 pts avg on six knowledge-work benches, 6.5% fewer tokens. Their PI suite scores 59.3 at $0.13/task vs Claude Fable 5 at $8.19. JobBench 62.9. Weights coming to Hugging Face.
Paper Instruments · paperinstruments.com ↗ (opens in a new tab)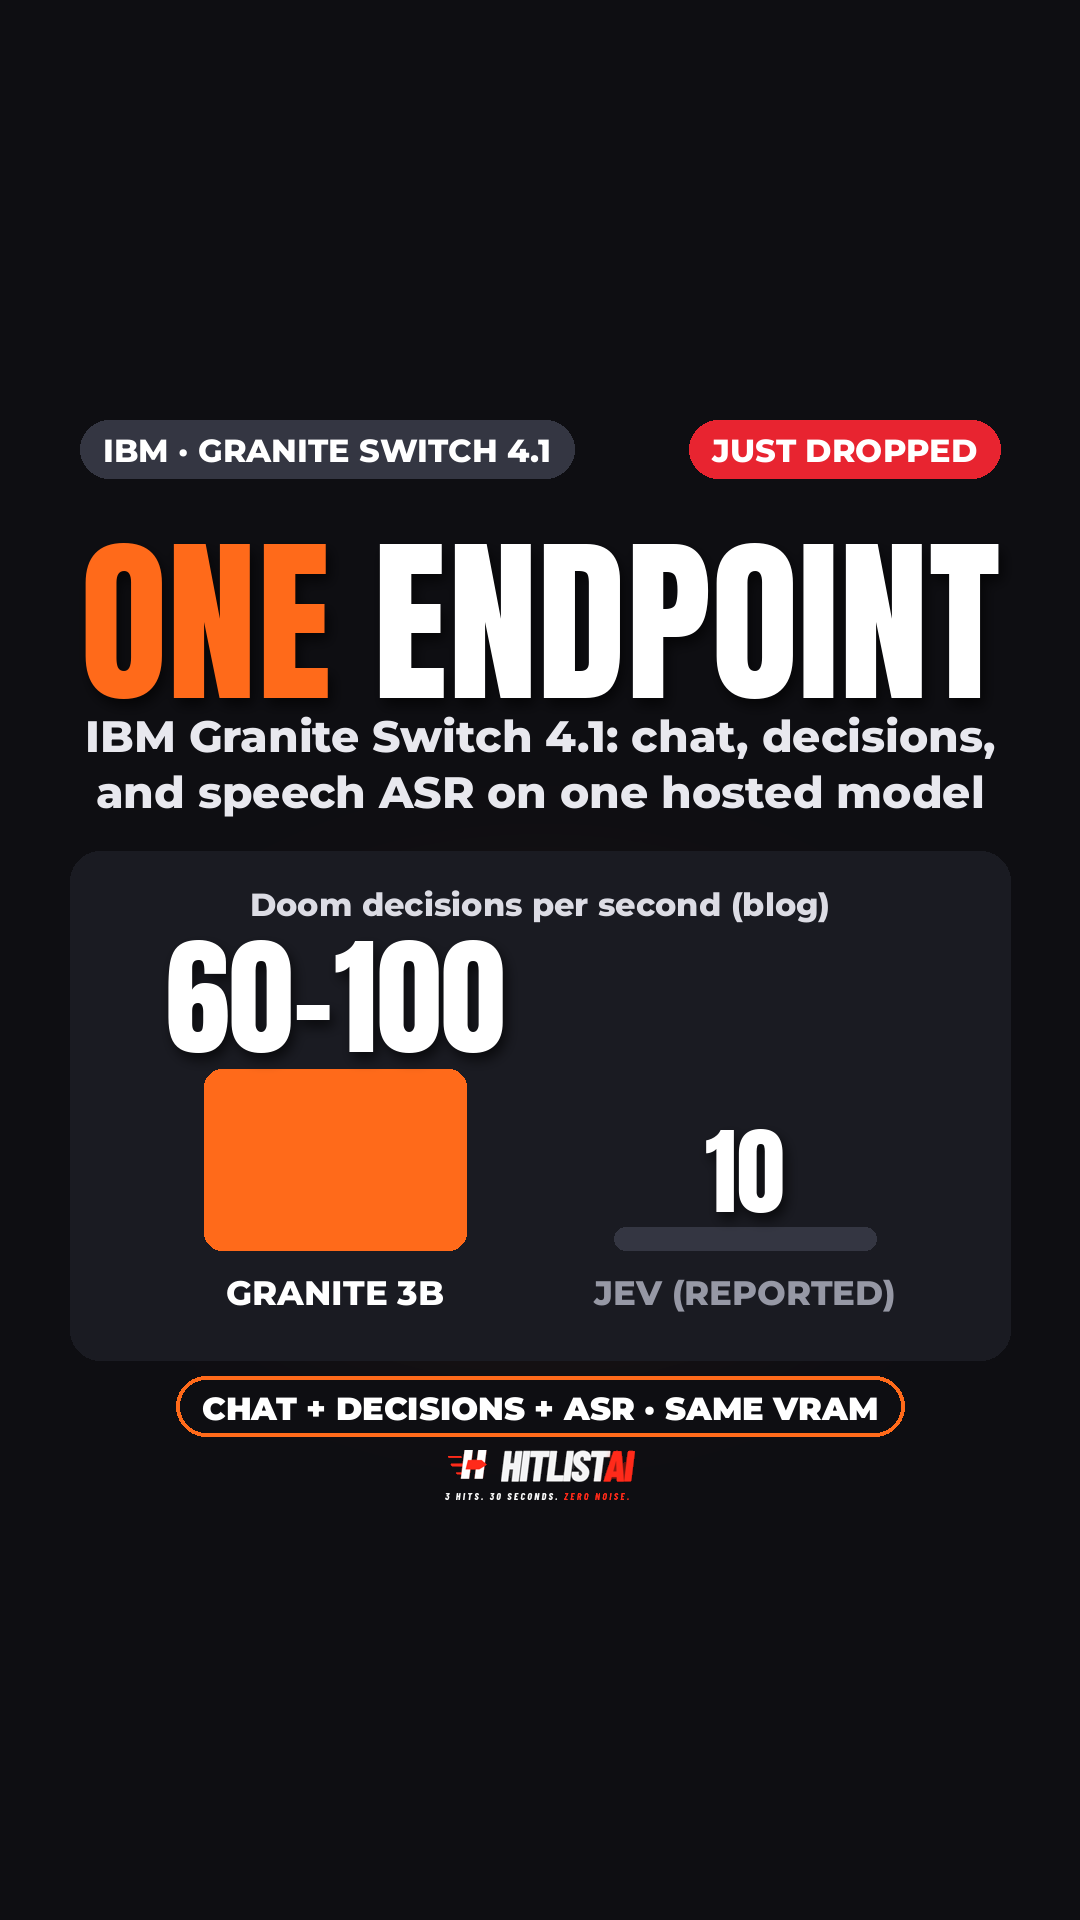
IBM Granite Switch 4.1: chat, decisions, ASR in one endpoint
IBM's Granite Switch 4.1 packs chat, a Decision aLoRA, a Guardian safety adapter, and Granite-Speech-5.0-Turbo-CTC (fastest on OpenASR per IBM) into one endpoint at ~the same VRAM as the base. A 3B Doom demo hits 60–100 decisions/sec vs Jev's reported 10.
IBM Granite / Hugging Face · huggingface.co ↗ (opens in a new tab)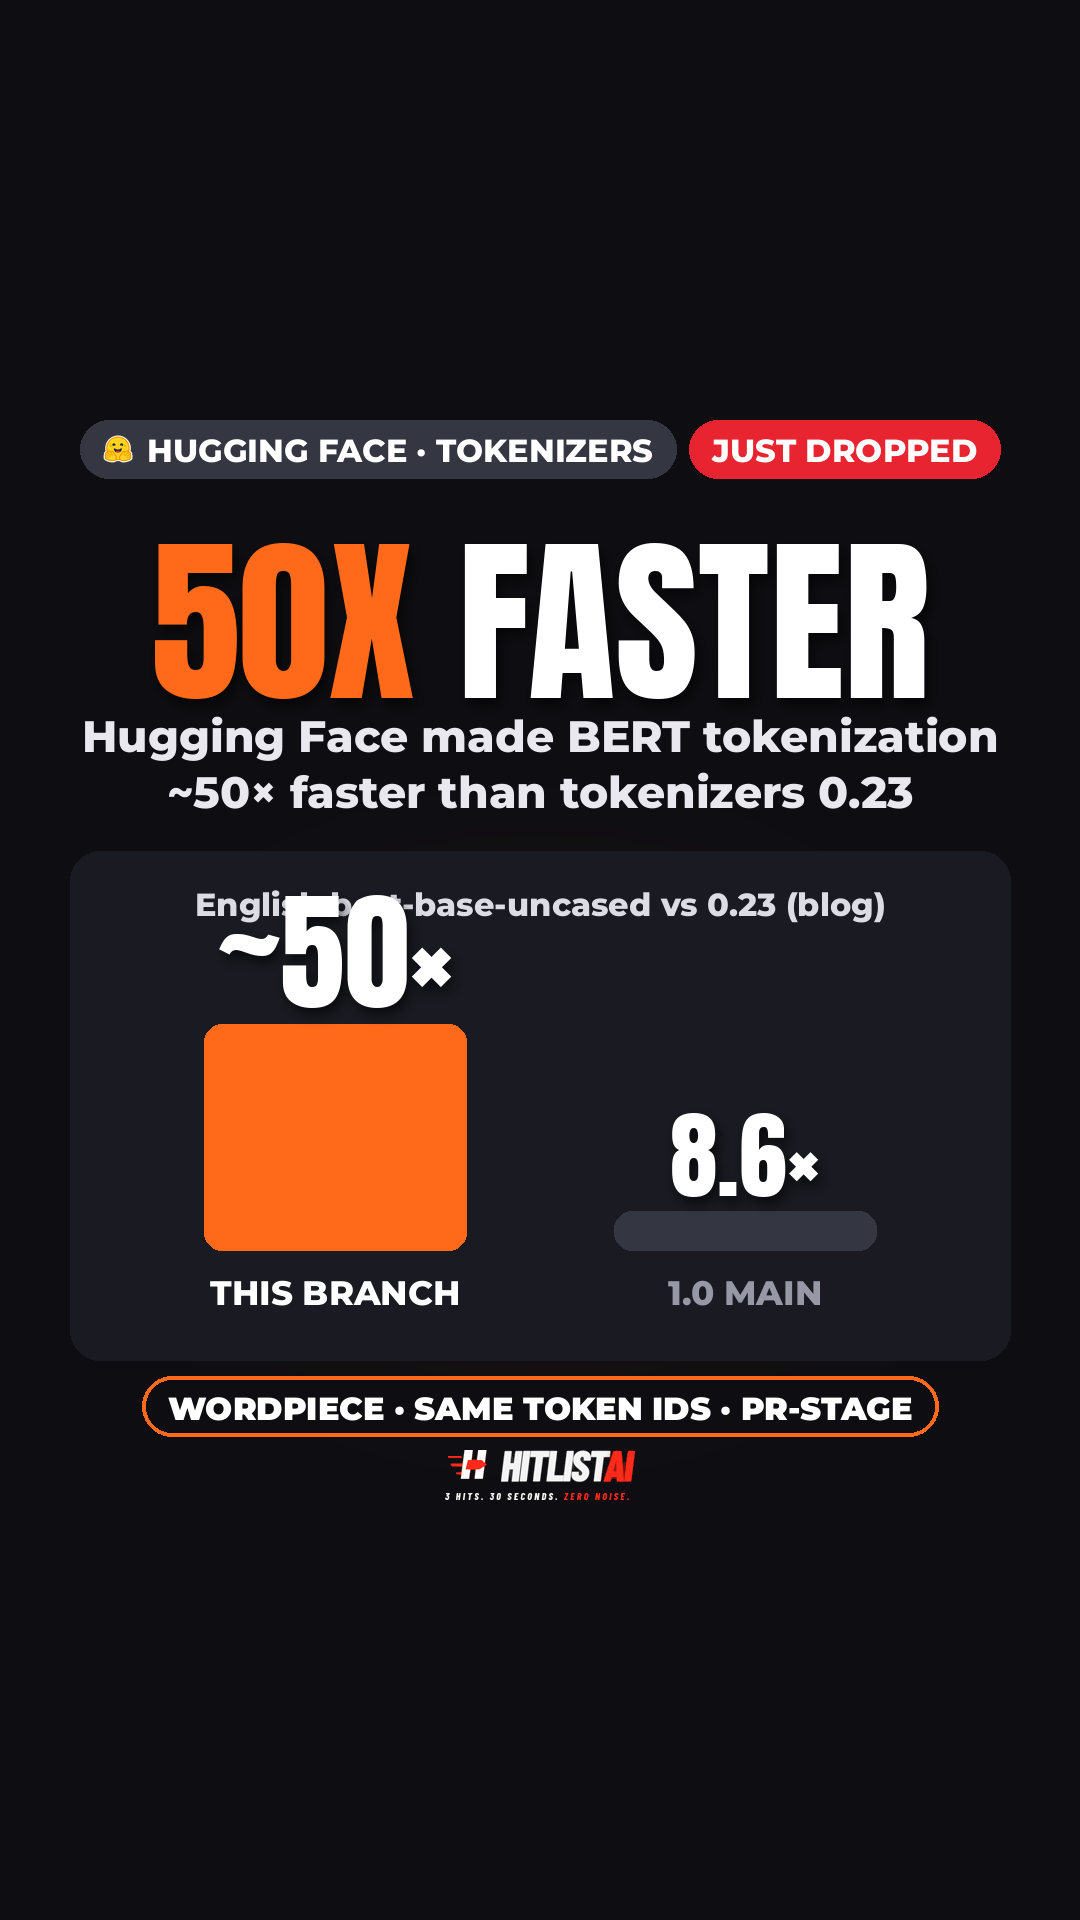
Hugging Face: BERT tokenization ~50× faster than 0.23
Hugging Face's tokenizers work made BERT (WordPiece) encoding about 50× faster than v0.23 (English chart: 50.8×). Normalization was ~88% of encode time, now ~13%; token ids unchanged. WordPiece still drives ~627M Hub downloads/month. Still a PR at blog time.
Hugging Face · huggingface.co ↗ (opens in a new tab)